The fastest way to create an unreliable AI workflow is to automate the visible middle and leave the boundaries undefined. A prompt goes in. An answer comes out. The demo looks smooth. Nobody has specified which inputs are allowed, which errors matter, who approves consequential outputs or how to stop the system when the surrounding process changes.
A pre-automation audit makes the workflow explicit before software increases its speed and reach. It is not a certification and it does not guarantee safety. It is a practical gate for ordinary teams deciding whether a bounded task is ready for assisted drafting, supervised automation or no automation at all.
Start with one real unit of work
Choose a completed, ordinary case—not the cleanest example and not the most catastrophic exception. Reconstruct what actually happened from intake through final use. List every document, message, database, judgment, approval and downstream action.
Name the unit precisely: “draft a first-pass summary from these four approved documents” is auditable. “Handle research” is not. The broader the verb, the easier it is for an automation to cross hidden boundaries.
Mark where professional judgment, consent, legal authority, safety or money enters the process. Those are not automatically forbidden zones. They are places where a generic success metric such as time saved is insufficient.
Map inputs, transformations and consumers
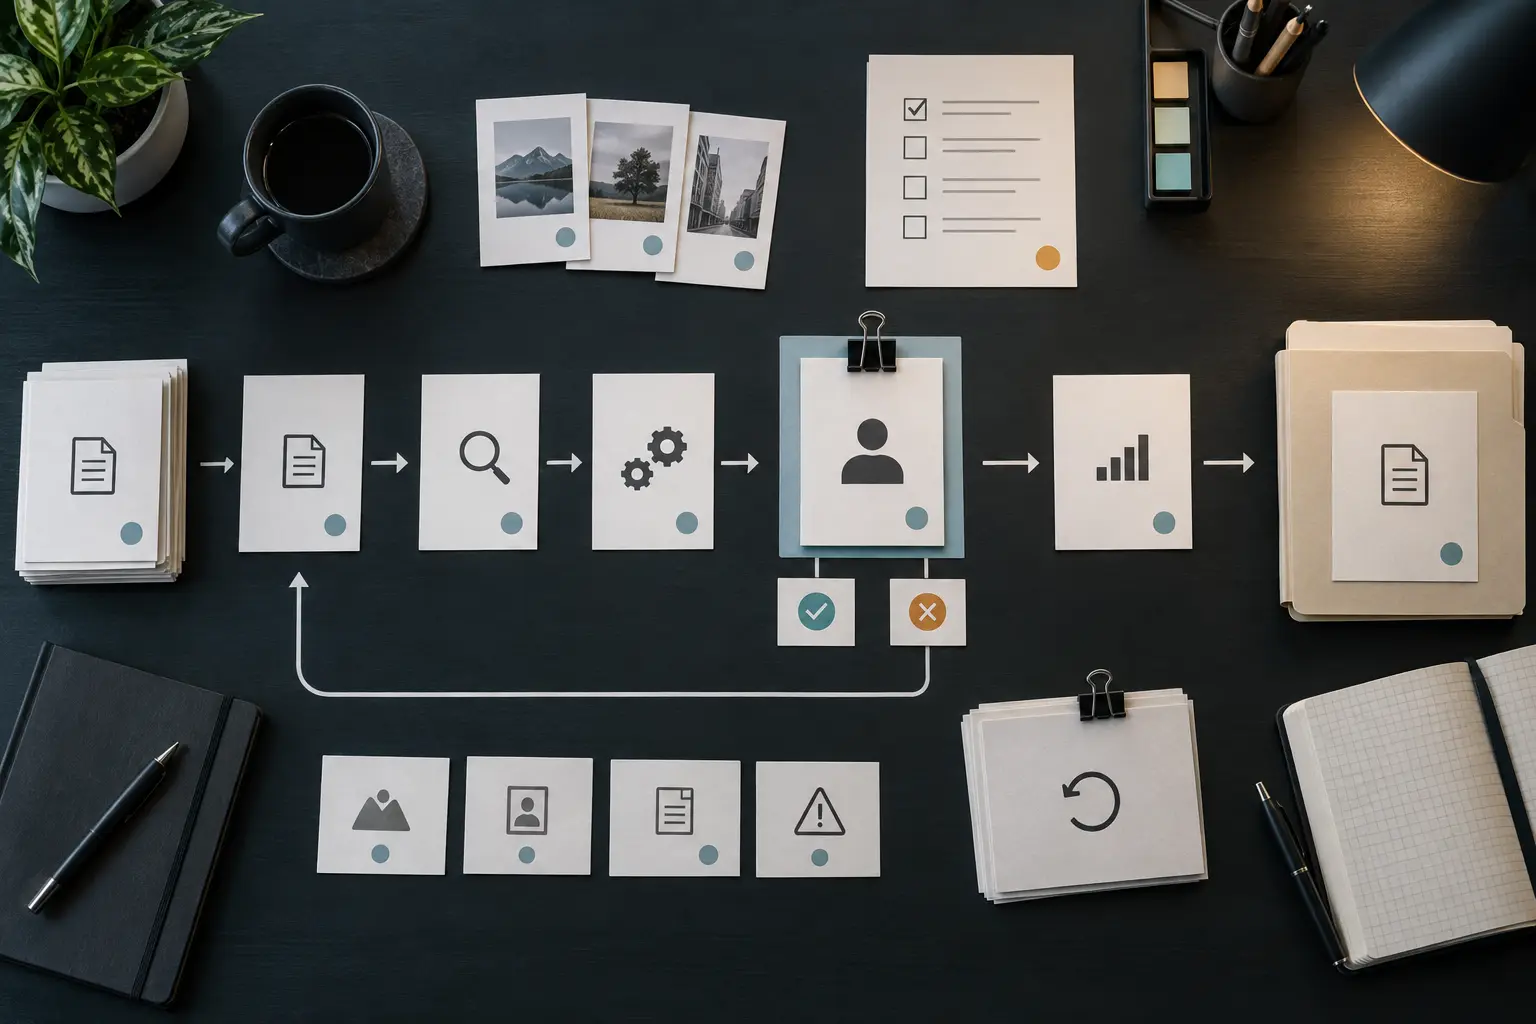
Create a simple chain with five columns: input, source of authority, transformation, reviewer and consumer. If a field comes from a person, distinguish what they reported from what was verified. If a model extracts a value, preserve the document and locator that carry it.
Inputs need acceptance rules. Define file types, date limits, required fields, source classes, privacy constraints and conditions that force rejection. “Use whatever is attached” turns missing context and poisoned context into valid data.
Outputs need a consumer. A private draft reviewed by an expert has a different risk surface from a message sent to a client, a public page, a code change or an update to a system of record. The same model answer changes meaning when permission to act is added.
Write the failure catalog before the prompt
List credible failures in the language of the work. Do not stop at “hallucination.” The system may use an outdated document, combine two people, miss a negation, produce a plausible but unsupported number, disclose private data, follow instructions embedded in an attachment, omit an exception, overwrite a human change or complete the wrong case.
For each failure, record severity, detectability, exposure and recovery. A frequent error caught before use may be tolerable. A rare silent error that changes a payment or safety decision may make the task unsuitable for autonomous operation.
The NIST AI Risk Management Framework organizes work around Govern, Map, Measure and Manage. Its Generative AI Profile adds risks including confabulation, data privacy, information integrity, information security, harmful bias and human-AI configuration. Use those as prompts for the catalog, not as a claim that checking a framework box resolves the risk.
Build a small representative test set
Collect examples that represent normal volume, edge cases and known past failures. Remove or protect personal data according to the real policy. A useful starter set may have twenty to fifty cases if the task is narrow; high-stakes systems require substantially more disciplined evaluation.
Include missing fields, contradictory sources, low-quality scans, unusual formatting, stale documents and instructions that should not be followed. Add at least one case where the correct behavior is to stop and ask for a human.
Freeze the test set before tuning the workflow. If every failure immediately changes the examples used for evaluation, you can overfit the demo. Keep a holdout set for the final gate and record which model, prompt, tools and configuration produced each result.
Define acceptance criteria outside the model
Ask what a reviewer must be able to verify. Possible criteria include exact extraction accuracy, claim-to-source traceability, completeness of required fields, correct refusal conditions, privacy preservation, formatting validity and time to review.
A model grading its own work can help triage but should not be the sole judge of a consequential output. Use deterministic checks where possible: schema validation, allowed-domain lists, duplicate detection, calculation tests, file hashes and required citations. Use human review for meaning, context and judgment.
Record both false acceptance and false rejection. A system that avoids every risky output by refusing ordinary work may be safe in one sense and operationally useless. The target is not maximum completion. It is acceptable behavior within a defined boundary.
Design the human gate as a real control
“Human in the loop” means little if the person is rushed, lacks the source material or can only click approve. Define what the reviewer sees, what they must compare, which fields require explicit confirmation and how much time review is expected to take.
Place the gate before the irreversible or externally visible action. If a tool can send, publish, purchase, delete, change permissions or update a record, the approval must control that tool call—not merely review a draft after the action.
Use sampling only when the residual risk supports it. A 10 percent sample does not protect the individual case that causes a large loss. Some fields or actions may require universal review even when routine prose is sampled.
Give the workflow the smallest useful permissions
Separate reading from writing and drafting from acting. A system that needs to summarize files may not need permission to delete them. A system that drafts email does not automatically need permission to send. Use dedicated folders, test accounts, scoped credentials and allowlists where the platform supports them.
Do not place secrets in prompts or logs merely because the interface is private. Map what data leaves the organization, how long it is retained, which vendors or subprocessors receive it and which settings govern model training or history. If those answers are unknown, the audit is not complete.
Make the run reconstructable
Save enough information to explain a consequential result: case ID, time, input versions or hashes, model and tool versions, prompt or workflow version, retrieved sources, output, validation results, reviewer and final action. Avoid logging private content that is not required for accountability.
Connect important factual claims to an evidence ledger. A log proves what the system saw. It does not prove that the source supported the conclusion.
Set retention and access rules. Logs that nobody can query do not support incident response. Logs copied everywhere create a new privacy problem.
Prove the rollback path
Write the stop condition, the person authorized to invoke it and the steps required to return to manual work. Preserve the last known-good workflow version. Back up data before testing any write path. Use idempotent operations or transaction boundaries where possible so a retry does not duplicate actions.
Run one controlled rollback before launch. Disable the automation, restore the previous version and complete one case manually. If that process depends on the only person who is away, the rollback is not operational.
Launch in three stages
- Shadow: run the workflow without allowing its output to affect the real process. Compare it with completed human work.
- Assist: let it draft or extract while a qualified person reviews every case and remains the actor.
- Bounded automation: permit only the actions that met the gate, with monitoring, limits and a tested stop path.
Do not promote stages because a deadline arrived. Require evidence: test performance, review burden, incident count, unresolved failure classes and downstream feedback. Record the decision in an AI decision record.
Monitor drift in the work, not only the model
Models change, but so do forms, policies, customer behavior, data sources and staff habits. Track input rejection rates, reviewer corrections, unsupported claims, refusals, latency, tool failures and reversals. A stable aggregate score can hide a new high-severity error.
Create refresh triggers: a model update, prompt change, new document type, policy revision, permission expansion, material incident or sustained correction trend. Re-run the holdout set and review the failure catalog before restoring normal operation.
Use the final four-way decision
- Automate: the task is bounded, reversible, measurable and low enough risk for the tested controls.
- Assist: the system saves effort, but a qualified human must verify every consequential output.
- Redesign: the task could work after cleaner inputs, smaller scope or better permissions.
- Do not automate: the judgment, authority, privacy exposure or silent-failure cost exceeds the demonstrated control.
The strongest audit result may be a smaller automation than the one first imagined. That is not a failure of ambition. It is evidence that the workflow was understood before speed multiplied its mistakes.
Research and implementation notes
- National Institute of Standards and Technology, AI Risk Management Framework, for the Govern, Map, Measure and Manage structure.
- NIST, Generative Artificial Intelligence Profile, July 2024, for generative-AI risk categories and actions.
- NIST AI Resource Center, AI RMF Playbook, for voluntary implementation suggestions.
- For failure discovery before launch, run the pre-mortem protocol.
- For the responsibility boundary, read Automation Does Not Remove Responsibility.
END OF FIELD GUIDE 048
Keep the question. Test the model.
Choose the narrowest claim the evidence can carry, then leave room for revision.